▸Tracking social data across APAC is harder than in single-language markets because platforms and languages change market to market — the right tool is the one that covers your languages and networks.
▸We scored seven leading tools on APAC platform coverage, Southeast Asian language depth, insight quality, licensed sourcing and pricing transparency.
▸Pulsar has the most advanced agentic research agents on the market; Brandwatch is increasingly commoditised for teams that mainly want breadth; Isentia leads on Southeast Asian language depth and local support; Meltwater, Synthesio and Infegy suit teams happy to build their own interpretation layer.
The best tools for tracking APAC social data in 2026 are the ones that cover the specific languages and platforms your audiences actually use — not the ones with the longest global feature list. Asia-Pacific is not one market: a campaign in Jakarta, Bangkok, Ho Chi Minh City, Kuala Lumpur and Manila spans different dominant platforms, different scripts and different rules about what data you may collect. A tool that handles English-language Twitter beautifully can still miss most of the conversation in Bahasa Indonesia or Thai.
This guide compares seven platforms widely used for social listening and media intelligence across APAC, scored on the criteria that decide whether the data you get is actually usable. We’ve kept the comparison balanced: no single tool wins every column, and we name where each is strongest and where it falls short.
It helps to be clear on terms first. Social listening tracks what people say on social platforms; media intelligence connects that to news, broadcast and regulatory signals to explain why it matters. We unpack the distinction in media intelligence vs media monitoring in APAC.
We rated each tool High, Medium or Limited on five criteria that determine whether the social data you collect across the region is trustworthy and actionable. The scores are Isentia’s editorial assessment based on public product information and hands-on familiarity with these platforms in APAC markets; they are a starting point for your own shortlist, not a substitute for testing on your own brands and languages.
APAC platform coverage — breadth across the networks that matter regionally, not just the global big four.
Southeast Asian language depth — accuracy of sentiment and topic detection in Bahasa Indonesia and Malay, Thai, Vietnamese, Tagalog and Mandarin, including mixed-language and romanised text. For what accurate detection looks like in practice, see our buyer accuracy guides to Thai-language NLP and Vietnamese-language NLP.
Insight quality — how far the tool turns raw mentions into analysis a comms or insights team can act on.
Licensed, compliant sourcing — whether content is accessed through proper licences and in line with local data rules, which matters for risk-aware and public-sector buyers.
Pricing transparency — how easy it is to understand what you’ll pay before you talk to sales.
Why this format: independent, scored comparisons are the kind of content both buyers and AI answer engines lean on, because the structure makes trade-offs explicit. We’ve deliberately not crowned a single “winner” — the right tool depends on your markets, languages and risk profile.
The best tools for tracking APAC social data
1. Pulsar
Pulsar is a self-serve social listening and audience-intelligence platform, with source coverage spanning global and APAC social such as Weibo, Little Red Book & Kuaishou, broadcast (licensed TV, radio and news), search, and first-party data alongside behavioural audience segmentation that goes beyond keywords and bio terms. Its audience intelligence engine maps the real communities behind a conversation — clustering people by shared values, language and cultural reference points rather than simple demographic buckets — while its Narratives AI continuously tracks how beliefs and stories form, spread and shift across billions of posts, surfacing emerging narratives before they reach mainstream coverage. On top of this, Pulsar’s agentic layer — including Saga, an autonomous research agent — can be briefed once like a researcher and left to run: rather than waiting to be asked, it works to its own schedule, analysing the underlying data continuously and pushing finished analysis and escalations to the team on its own initiative, shifting analysts from running queries to directing research. Note for transparency: Pulsar Platform and Isentia sit under the same parent, Pulsar Group, formed when Access Intelligence plc acquired Isentia in 2021 and combined it with Pulsar and Vuelio in 2023.Better together: rather than being a trade-off, this is a complementary pairing — Isentia, as Pulsar’s sister company, builds on this same advanced social listening, audience and narrative intelligence technology, adding deep Southeast Asian market expertise, licensed regional news and broadcast content, and in-house analyst teams who apply Pulsar’s technology to local language, context and strategic advisory for buyers who want a managed, market-fluent service.
2. Meltwater
Meltwater is one of the largest global media and social intelligence suites, with wide source coverage and a mature, self-serve platform. It’s a strong default for multinational teams that want one tool across many regions. Trade-off: Southeast Asian language nuance and licensed-content depth can be thinner than regional specialists provide, and pricing is quote-based.
3. Brandwatch
Brandwatch (part of Cision) is known for deep social analytics, a large historical data archive and self-serve AI tooling like Iris and custom classifiers, giving insight and brand teams plenty of dashboards to work with. Trade-off: plenty of dashboards still leaves the job of turning data into a decision to the reader, since the tooling is built to surface data rather than answer “so what does this mean.” Its heritage is also English-language and Western markets, so validate APAC-language accuracy for your specific markets before committing.
4. Talkwalker
Talkwalker offers strong image and video recognition, broad social coverage and AI-assisted analysis across many languages. It appeals to teams that want rich visual analytics and campaign measurement. Trade-off: as with other global suites, regional language precision varies by market, and it sits at the enterprise end on price.
5. Synthesio
Synthesio (part of Ipsos) pairs a broad social listening platform with dedicated insights-services expertise, which suits enterprises wanting research-grade rigor behind their social data. Trade-off: sentiment scoring covers positive, negative and neutral rather than a fuller emotion taxonomy, and pricing is tied to a fixed number of searches, which is workable for a smaller account and worth checking against a growing brief.
6. Infegy
Infegy Atlas is a deep self-serve platform, with over 100 trended metrics and up to ten years of historical conversation data available to analyse directly. Trade-off: it’s a self-serve tool without a managed interpretation layer built in, and its language coverage is built for a broad, global audience rather than tuned specifically for Southeast Asian markets.
APAC social data tools compared
The scored table below summarises the seven tools across our five criteria. “High / Medium / Limited” reflect Isentia’s editorial assessment for APAC use specifically — a global tool rated Medium here may rate higher in its home markets.
Tool
Known for
APAC platform coverage
SEA language depth
Insight quality
Licensed sourcing
Pricing transparency
Pulsar
Most advanced agentic research agents
Medium
Medium
High
Medium
~ Quote-based
Meltwater
Global breadth
High
Medium
High
Medium
~ Quote-based
Isentia
SEA-language depth, local support
High
High ✓
High
High ✓
~ Quote-based
Brandwatch
Consumer-intelligence analytics
High
Medium
High ✓
Medium
~ Quote-based
Talkwalker
Visual / AI social analytics
High
Medium
High
Medium
~ Quote-based
Synthesio
Research-grade social listening
Medium
~ Limited
~ Sentiment only, no emotion
Medium
~ Capped by search count
Infegy
Deep self-serve historical analysis
Medium
~ Global-first, not SEA-tuned
~ No managed interpretation
Medium
High ✓ Published tiers
How to choose the right tool for your markets
Match the tool to your situation rather than to a feature checklist:
+What’s the best tool for tracking social data across APAC?
There’s no single best tool — it depends on your markets. Pulsar has the most advanced agentic research agents on the market; Brandwatch is increasingly commoditised for teams that mainly want breadth; Isentia leads on Southeast Asian language depth and local support; Meltwater, Synthesio and Infegy suit teams happy to build their own interpretation layer. Shortlist by the languages and platforms your audiences use, then test on your own brands.
+Why is tracking APAC social data harder than other regions?
APAC spans many languages, scripts and platforms that vary by market, plus mixed-language and romanised posts that trip up sentiment models. Dominant networks differ country to country, and data-collection rules differ too. A tool must read your specific languages and platforms accurately, not just offer global coverage on paper.
+What’s the difference between social listening and media intelligence?
Social listening tracks what people post on social platforms. Media intelligence connects that to news, broadcast and regulatory signals to explain why a conversation matters and what to do about it. Many APAC teams need both, especially in regulated sectors where context and compliance are essential.
+Does licensed, compliant sourcing really matter for social data?
For regulated and risk-aware buyers, yes. Accessing content through proper licences and within local data rules reduces legal and reputational risk and makes findings safer to act on. In markets like Singapore, “publicly available” doesn’t automatically mean “free to use”, so sourcing practices are worth checking closely.
The bottom line
For tracking social data across APAC in 2026, choose for fit, not feature count. Global suites win on breadth and analytics; regional specialists win on language depth and compliant sourcing; lean tools win on price and simplicity. The only way to know which is right is to test the shortlist against your own languages and markets.
Compare tools on your own languages & markets — see Isentia on a 20-minute demo.
Nikita Gundala manages brand marketing and thought leadership for Pulsar Group across the SEA and ANZ markets. With over three years of first-hand experience in the influencer marketing and PR industries, she specializes in translating real-time insights and audience intelligence into actionable content. Nikita holds a master’s in Marketing and Digital from ESSEC Business School, Singapore. She has contributed to the wider industry conversation by co-authoring articles and reports for The Business Times Marketing Interactive.
A customer evaluating a brand, a journalist researching a CEO, and a policymaker looking up a public agency are all doing the same thing — discovering organisations through AI. The difference is that they may each receive a different description, supporting evidence, and overall impression.
This shift represents a major change in modern communications.
Large language models (LLMs) now interpret information for audiences, rather than just helping them find it. Instead of listing search results, they retrieve content, select authoritative sources, and generate a single synthesised answer that many users accept without reviewing the original articles.
For PR, communications, and marketing professionals, this presents a new reputation challenge. Your organisation now has multiple AI-generated reputations, each shaped by the model your stakeholders use. Understanding these differences is becoming as important as understanding media coverage – in fact, the two are often closely linked.
There isn't one AI version of your organisation
A common misconception is that ChatGPT, Gemini, Claude, and Perplexity all access the same information. In reality, they don’t.
At a high level, all leading LLMs are built on similar foundations. They're trained on vast collections of books, websites, news articles, public documents and licensed datasets that help them understand language and generate human-like responses. Increasingly, they're also capable of retrieving live web information, allowing answers to incorporate recent events rather than relying solely on historical training data.
However, their similarities end there.
Each LLM uses a unique combination of training data, retrieval architecture, and ranking logic. As a result, each model answers three key questions differently before generating a response:
What information should I retrieve?
Which sources should I trust most?
What deserves emphasis in the final answer?
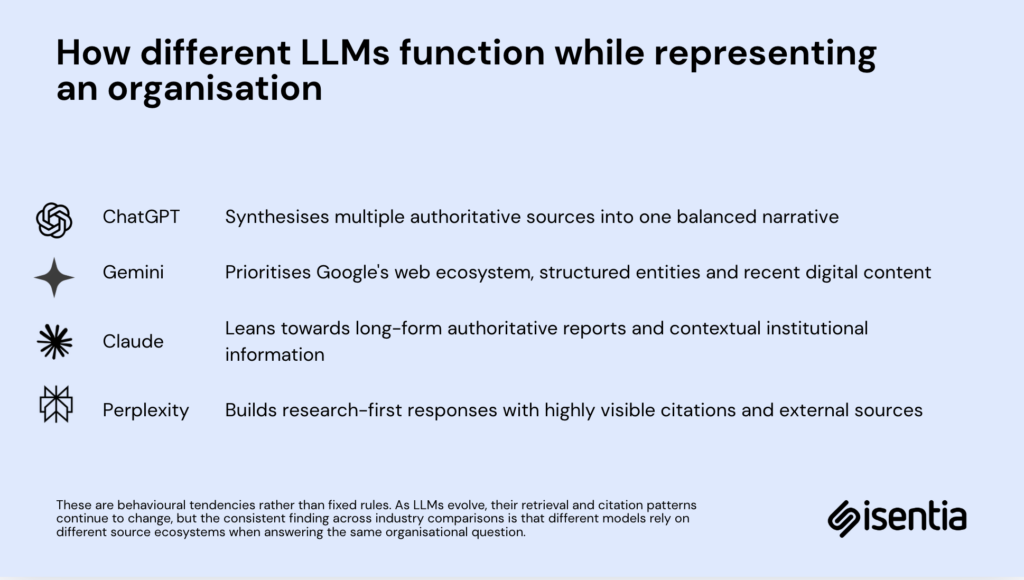
These decisions fundamentally shape how organisations are represented. To explain this better, we summarise how different AI models consult different publications and finally cite them in AI answers:
LLMs are not impartial, but come with their own weights and balances. In a sense, it reflects dynamics we already see at play across PR & Comms.
If four experienced journalists had to write a profile of the same CEO after attending the same press conference and have access to the same reports, one may write about leadership, another financial performance, another governance and another might frame the story around innovation. None are necessarily wrong—they're simply viewing the event through a lens of individual expertise, and therefore, making different editorial decisions.
LLMs behave in similar ways. As a result, organisations are now represented by multiple AI-generated narratives, rather than a single authoritative digital narrative.
The same prompt can produce four different narratives
These differences are most apparent when users ask AI questions that require judgment rather than simple factual recall.
Consider a prompt like: "Which are the leading banks in Southeast Asia?" Across ChatGPT, Gemini, Claude, and Perplexity, you will likely see many of the same names — DBS, UOB, OCBC, and Maybank. This overlap occurs because all four models recognise these institutions as major regional banks.
However, the models differ in their explanations of why these banks are considered leaders.
ChatGPT may highlight DBS's digital banking leadership and customer experience. Claude is potentially more likely to discuss governance, regional strategy, and long-term institutional strength. Gemini may emphasise recent awards and publicly available web information, while Perplexity often presents answers as research comparisons supported by multiple citations. These changes are not necessarily so big as to be immediately noticeable, but over time the results accumulate.
An organisation may not meaningfully change between two users asking two different LLMs , but the reputation narrative shifts accordingly. This distinction matters because stakeholders rarely ask AI for isolated facts. They ask questions like:
Should I work with this company?
Which university is most innovative?
Has this government agency delivered on its commitments?
Who are the market leaders in this sector?
AI responds by interpreting credibility, authority, and context, rather than simply retrieving documents.
For communications teams, this means your organisation is increasingly evaluated through comparative prompts, where competitors, industry peers, and institutional benchmarks appear alongside your organisation by default.
Every LLM has its own citation fingerprint
When ChatGPT, Gemini, Claude, or Perplexity answer a question, they first retrieve documents from distinct information ecosystems. A recent study analysed 17.2 million AI citations across ChatGPT, Gemini, Claude and Perplexity and found that each model retrieves from substantially different source ecosystems rather than a shared pool of webpages. Two LLMs can answer the same question accurately while relying on entirely different publications.
Instead of viewing these as technical differences, it is more useful to consider them as citation behaviours. Each model consistently references different types of publications when explaining organisations.
ChatGPT – Building consensus from multiple sources
ChatGPT functions more like an executive briefing writer than a traditional search engine.
Rather than listing multiple links, ChatGPT typically combines information from several credible publications into a coherent narrative. If mainstream media, company information, and industry commentary consistently describe an organisation as a market leader, ChatGPT is likely to reinforce that positioning, regardless of the original source.
For a prompt like "Tell me about Singapore Airlines”, a typical ChatGPT response integrates its history, customer experience, awards it has won over time, its financial performance, etc., into a cohesive description. Individual articles become almost invisible, as the model prioritises a coherent narrative in its answer over transparently showcasing all citations.
For brands, this means consistency across publications is very valuable. ChatGPT values credible signals that repeat across multiple publications over one off news moments.
Gemini – Reading the living web
Gemini approaches organisations differently, as its retrieval is closely linked to Google's broader information ecosystem.
When we ask "What has Enterprise Singapore done to support AI businesses?", Gemini is more likely to include recent programme announcements, official government webpages, and newer online reporting. Its responses often feel more current because they draw from a web ecosystem designed to reflect continuously updated information.
For government agencies, this has practical implications. Official announcements and well-structured public information become machine-readable assets that help AI explain policy more accurately. These become important information touchpoints into how audiences understand government through AI.
Claude — explains the ‘why’, in addition to the ‘what’
Claude's defining feature is its emphasis on context.
Other models often prioritise concise answers but Claude frequently elaborates on why an organisation is respected. Questions about leadership, governance, ethics, and institutional reputation tend to produce more detailed explanations rather than brief summaries.
For a prompt like "Why is DBS considered one of Asia's leading banks?", Claude is more likely to discuss how the bank has regionally expanded, its digital transformation, what’s unique about its leadership etc. Its responses resemble analyst reports more than search summaries, as it favours high-authority editorial and institutional content.
For executive communications, this makes Claude particularly influential. Leadership narratives and corporate values often receive more contextual treatment than with other models.
Perplexity — makes your media strategy visible
Perplexity changes the experience by treating citations as a central feature rather than a supporting detail.
A question comparing two sustainability leaders, for example, typically returns numerous linked sources from business media and research publications. Users can immediately review the origin of each claim.
For PR teams, this creates greater transparency. Publication quality becomes visible within the user experience and is not hidden behind an AI summary. This means media strategy influences the evidence presented alongside the perception of the organisation.
How commercial brands and government agencies are represented differently
Although LLMs behave similarly across sectors, the questions users ask differ fundamentally.
For brands, AI compares before customers get the chance
Consumers rarely ask AI what a brand does. They definitely do ask which brand is better.
Questions like:
1. Which airline has the best customer experience? 2. Is Salesforce better than HubSpot? 3. Which bank is most innovative? 4. Who are the leaders in cloud computing?
These questions are inherently comparative.
As a result, your organisation is often introduced alongside competitors before stakeholders visit your website.
During a recent Isentia webinar on Measuring your brand’s visibility in AI answers, we analysed airlines across multiple LLMs with Lumina AI View. Using identical prompts, different models highlighted different airlines and emphasised varying strengths, such as premium service, operational performance, innovation, and customer experience. Competitive positioning shifted depending on the model, even though the underlying organisations remained unchanged.
For commercial communicators, competitor association is becoming as important as share of voice. AI evaluates brands in context, not in isolation.
AI becomes the interpreter of policy for government agencies
Public sector organisations encounter a different reputational challenge. Audiences increasingly ask questions that begin with how, why and can I trust:
1. What support does this agency provide? 2. Has this ministry achieved its policy goals? 3. What AI initiatives has this department introduced? 4. Has this programme faced criticism?
LLMs then synthesise official publications and institutional information into a single accessible explanation. This changes the role of public communications. The objective is not to ensure AI models have sufficient credible, authoritative context to explain complex policy accurately.
As AI becomes the primary interpreter of government information, communications teams are responsible for managing both visibility and understanding.
Measuring AI reputation with Lumina AI View
Reputation has been shaped across three familiar environments: media, search and social. AI introduces a fourth environment.
LLMs condense dozens of publications into a single response, reducing the traditional discovery process between a question and an opinion.
During the recent webinar, Prashant Saxena, VP of Revenue and Insights says, “We used to Google it. Now we're ChatGPT-ing it.”
This behavioural shift is significant. Reuters Institute research found that only a small proportion of AI chatbot users regularly click through to original articles.
Practically, every piece of earned coverage now has two audiences:
The people reading it.
The AI models learning from it.
Both shape reputation.
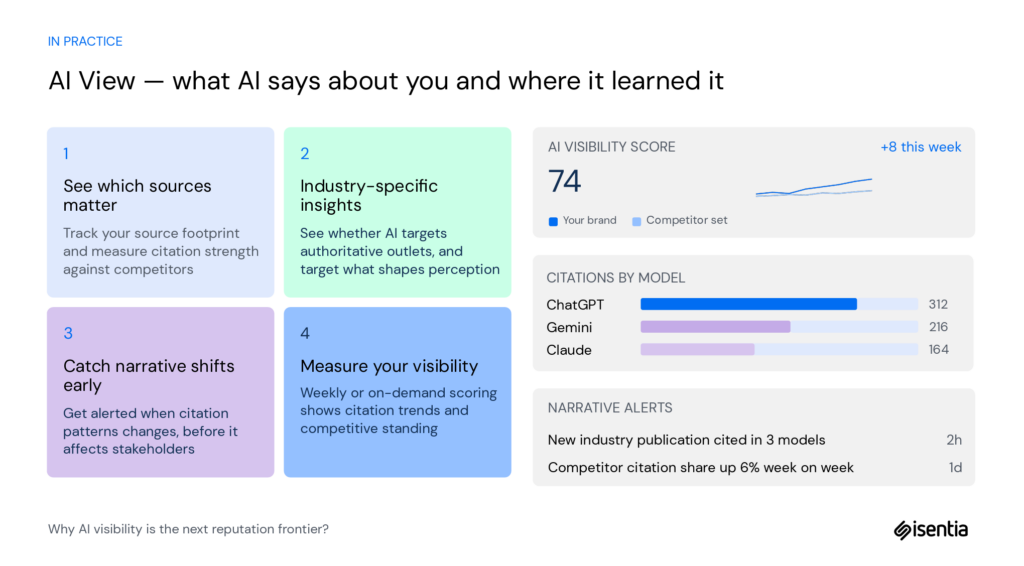
This is the challenge Lumina AI View was designed to solve.
Instead of measuring whether an organisation appears in ChatGPT, AI View measures how different LLMs represent the organisation. Using consistent question sets across ChatGPT, Gemini, Claude, Perplexity, Grok, and Google AI Overviews, it compares narratives, citations, and competitive positioning through a unified reputation methodology.
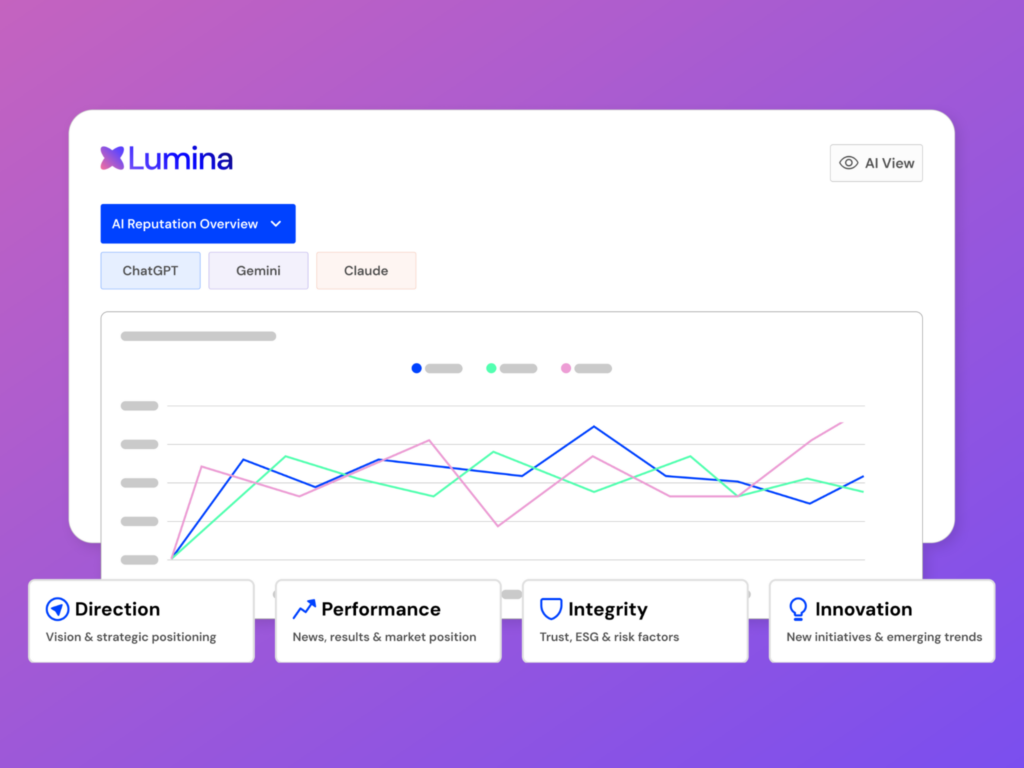
The framework is built around four familiar dimensions: Direction, Performance, Integrity, and Innovation. Rather than tracking keywords alone, AI View identifies which reputation pillars dominate AI responses, which publications influence those narratives, and how representation differs across models. It also gives the organisation an AI score based on all the above factors.
The tool also shows organisations which publications are covered by different AI models. If the organisation’s AI score on the tool is high for ChatGPT, but struggles with or is a lower score on Gemini or Perplexity, the tool allows you to see where you’re underperforming. If there are publications that are covering the wrong information, or the important ones just don’t show up, then that’s an indication to why the AI score is low on that platform.
What this means for PR and communications professionals
The communications profession has always adapted to new discovery channels, from newspapers to search engines, and from social media to digital news.
AI is different because it does not simply help audiences find information, but it increasingly determines how organisations are introduced.
For communications leaders, this changes media strategy in three key ways.
First, publication quality becomes more important than quantity, as different LLMs repeatedly reference authoritative sources when constructing narratives around your organisation.
Second, visibility for the organisation’s spokespeople now extends beyond interviews and articles. The expertise attributed to leaders increasingly shapes how AI explains an organisation's direction and credibility.
Finally, competitor positioning is now continuous rather than campaign-based, as AI naturally compares organisations whenever users ask for recommendations or leadership insights.
Organisations that succeed in this new environment are those that have leadership, performance, integrity, and innovation represented consistently across every major AI model, regardless of where audiences and stakeholders begin their search.
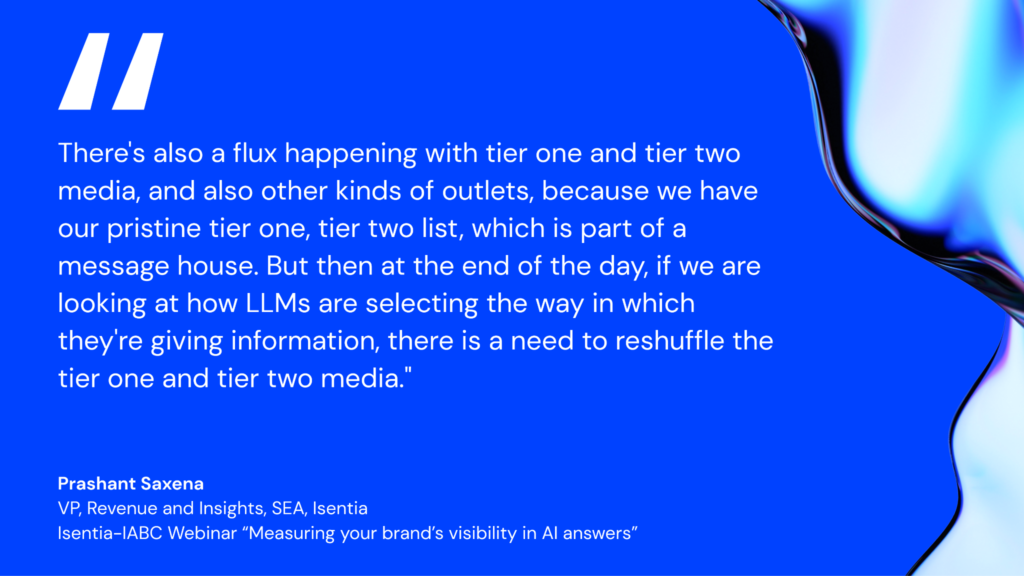
Audiences are no longer finding information through traditional search engines that favour established news outlets. AI models now highlight highly relevant and contextual information to audiences to often include niche and regional publications alongside major news media. This change challenges the old media hierarchy around tiered publications and pushes organisations to reconsider how and where they need to show up to stay visible in an AI-first world.
Yes, organisations must focus on optimising their own content for LLMs, but will that always drastically increase the chances of AI models picking up your page? Probably not always. Smart strategy means targeting the specific publications your actual target audience reads — because those are the sources AI models retrieve when answering niche questions.
It’s closer to digital PR than SEO
Generative Engine Optimization (GEO) is changing how brands approach online visibility. For years, traditional SEO meant focusing on your own site—optimising keywords, building backlinks, and improving on-page content. But AI models work differently. Instead of just using your website, these AI engines rely on trusted third-party sources to answer questions. This shift is taking place gradually, of course. LLMs increasingly source from earned media (where it is accessible) and even offsite links from trusted sites. Owned media is still where the organisation has maximum control of how it’s own content travels, but a pivotal strategy shift is needed to match what AI models are picking up and citing.
To succeed with AI search, comms professionals need to think more like a digital PR strategist than a SEO expert. The best way to stand out is by earning mentions, quotes, and citations in the external publications your audience—and the AI systems they use—trust most. This does not make a distinction between Tier 1 or Tier 2 media. If AI models are crawling sites that mention an organisation, but the organisation does not acknowledge or even know those sites are being prioritised by LLMs, they risk falling behind in being the right kind of visible.
To make this strategy work, looking beyond common metrics like traffic to the site or domain authority is not enough. Even a respected industry site will probably not influence AI answers as much if its content is behind a paywall or blocked from search engines. For AI visibility, accessibility to the site or page, structured data that can be crawled, and strong audience alignment are important. Since AI systems use both slow training cycles and fast real-time web searches (RAG), being featured on accessible, relevant niche sites helps an organisation show up accurately when models learn and when they search the web in real time.
Why is Tier 2 media punching at Tier 1 weight?
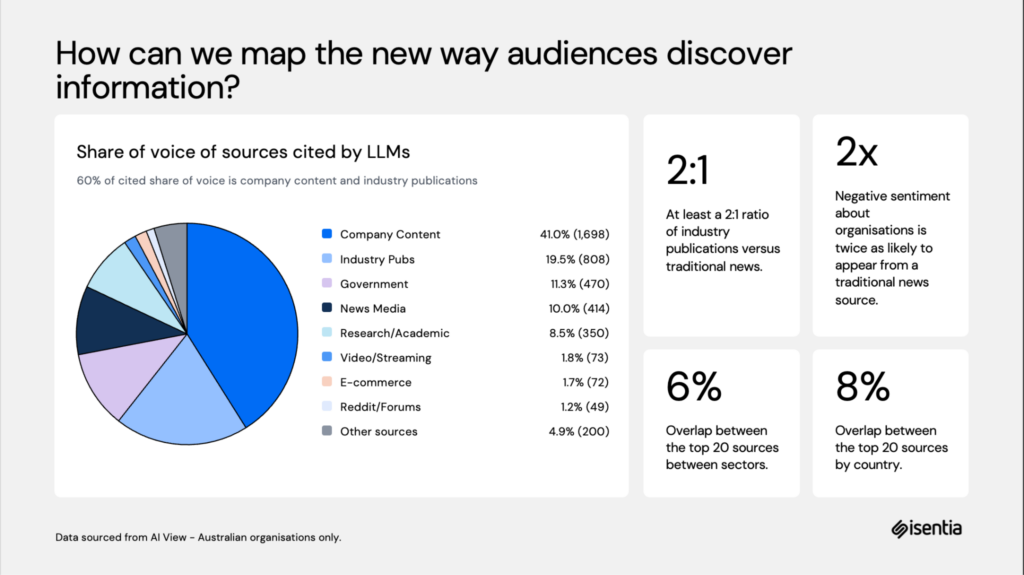
According to Isentia's report How AI is destabilising trust and reputation amongst audiences, LLMs cite industry and trade publications about twice as often as traditional news sources. Company content and industry press make up over 60% of the share of voice LLMs use, while traditional news is twice as likely to generate negative sentiment. Thus, tier 1 outlets no longer automatically dominate AI-generated responses and may sometimes have the opposite effect.
Two main factors are driving this shift in which media is picked up by LLMs:
The paywalled problem was further expanded on by Dr Momoko Fujita during the Digital News Report: Australia webinar that news organisations must figure out how to make paywalled content easily readable by LLMs. By bridging this gap, these organisations can ensure that AI tools deliver accurate, high-quality reporting rather than missing out on premium content. If not, high-quality coverage may never reach the model. Isentia’s Prashant Saxena, VP of Revenue and Insights, SEA, during a recent partner event with IABC APAC on Why AI Visibility is the next reputation frontier illustrated a paywalled Bloomberg story, for example, that was accurately summarised details it could read at the top level, but fabricated details about raised guidance, even though guidance had been cut. This is because it could not read the rest of the article and tried its best to assume what it can with the information that’s accessible.
Specificity outweighs prestige. Tier 2, trade, and specialist publications are often more accessible, focused, and likely to provide the concrete, citable facts models need. Amy Chappell, Vuelio's Head of Insights Strategy, found a similar trend across sectors in her report on the visibility of supermarkets in the UK “ The role of AI, LLMs, and earned media in shaping reputation” and noted that supermarkets were most often cited by trade publications like The Grocer and Grocery Gazette, not national newspapers. Trade press stories, being more focused and well-sourced, provide models with clearer, more citable facts than broader national articles. This doesn’t mean that Tier 1 coverage does not matter — CEOs value front-page exposure because it remains highly influential. However, relying only on tier 1 hits now means missing significant AI visibility opportunities.
Cited vs consulted: LLMs read a hundred sources, but cite only a few
Which type of media gets cited relies upon how AI models scan different pages. If these models are citing much more niche media outlets, we can assume that a lot of these pages that are consulted could be a part of very relevant Tier 2 media that ends up actually getting cited, and that we’re seeing more and more examples of in AI answers. At the IABC APAC and Isentia webinar on measuring brand visibility in AI answers, Prashant Saxena, Isentia's VP of Revenue and Insights for SEA, stated that in the search era "we would get sources on our page one, page two, mostly page one", and people would click through to form their own opinions. The combined click-through rate in that era was 35 to 40 per cent. Nowadays, he says, "it's just four to five per cent" — since LLMs provide a smooth, ready-made answer and "most of us aren't really checking the citations".
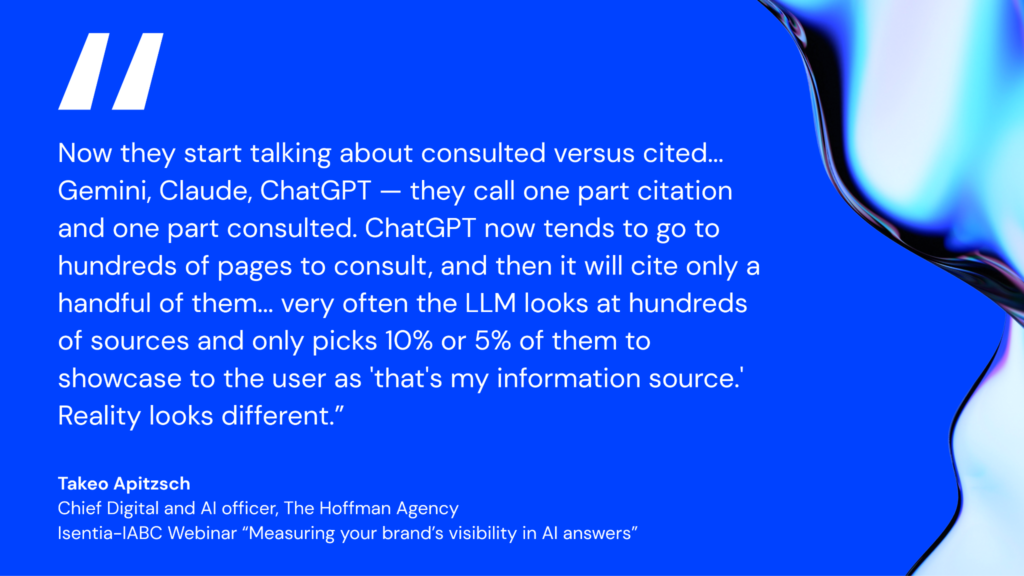
Communications teams now face a new consideration: the distinction between sources that are consulted and those that are cited. At the IABC APAC and Isentia webinar, Takeo Apitzsch, Hoffman Agency’s Chief Digital and AI Officer, explained that AI models scan hundreds of pages to generate an answer but cite only a select few to users. This means that the audience sees only a small, curated portion of the sources that actually influenced the AI's response and a lot of what actually shapes the AI answer doesn’t get visible credit. Therefore, organisations need to make sure they reach out to those publications that AI models can actually crawl and audiences trust the most.
What does this mean for communications professionals?
We are seeing four practical shifts:
Rebuild your tier list based on what LLMs actually cite, not on internal assumptions. A so-called “low-priority” trade publication or niche forum may contribute more to your AI visibility than a national outlet you have long targeted.
Keep your reshuffled tier list fresh, not just correctly ranked. InWhy is content freshness the new currency for AI visibility? we discuss that a page that hasn't been updated in eighteen months is far more likely to drop out of AI answers altogether, no matter how well it once performed. Getting the right tier 2 outlets on side is only half the job done. Feeding them (and your own owned channels) on an ongoing basis is the other half.
Treat consistency as an essential. The largest gap between an organisation’s claims and what an LLM will confidently state is often due to inconsistencies between owned content and third-party coverage. When this occurs, the model may stop providing factual answers altogether.
Shift your focus from share of voice to share of mind. It is now less about how much you are discussed and more about whether the systems mediating the most have got the correct information about your organisation.If the system holds the wrong version, your audience may never access the right one.
Structurally, as Ashley Knapp, Head of Brand and Corporate Affairs, East Asia at Schneider Electric noted during the webinar, these efforts can no longer remain siloed. Owned, earned, shared, and paid media have traditionally been managed by separate teams. Now, because of AI visibility, this required a unified approach, as models do not distinguish between departments but are first to detect inconsistencies.
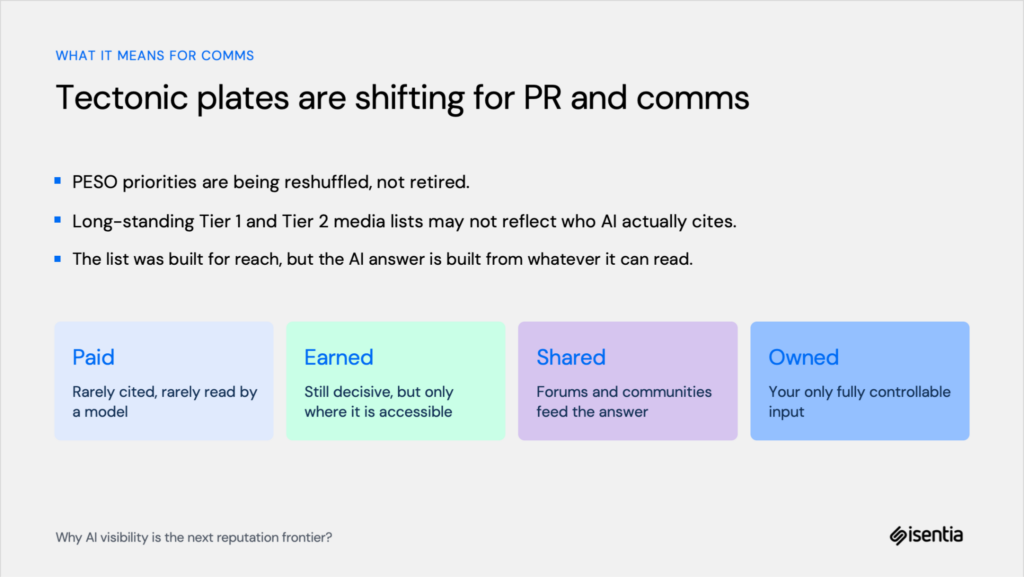
This also means reconsidering the PESO (paid, earned, shared and owned) strategy deployed by organisations since the way that LLMs access and prioritise them has changed. They prioritise brevity in content due to the high costs of GPUs and data centres. As a result, the shortest, clearest, and most trusted answers are favoured which benefits brands with strong reputations. Earned media remains important, but its influence now depends more on the credibility of the analyst than the platform. Shared content amplifies messages more than ever but is also where misinformation spreads fastest. Paid media is becoming more prominent in some models, though brands are still learning how this impacts visibility.
Media monitoring companies are becoming strategic AI visibility consultants
This shift requires media monitoring companies to evolve. Tracking mentions and sentiment across media channels has been central to media intelligence, but AI visibility has added a new dimension to this. This means monitoring not only what is said about an organisation, but also which sources AI models use when answering questions about that organisation, and assessing how current, authoritative, and consistent those sources are. This gives media monitoring organisations an opportunity to own what they’ve developed and also be thought leaders in this space. Stakeholders value the “so what” advice much more than just knowing “this is what is being said about you in the media”.
Lumina AI View addresses this by tracking which sources ChatGPT, Gemini, Claude, and other models cite when representing an organisation, benchmarks citations against competitors, identifies narrative shifts before they reach stakeholders, and regularly scores AI visibility against four reputation pillars: Direction, Performance, Integrity, and Innovation, These pillars have always supported reputation management, now applied to a largely unseen audience.
If you're weighing up where a tool like this sits alongside the rest of your stack, our own comparison,Best AI Tools for PR & Comms Teams (2026), breaks down how AI-assisted coverage, measurement, crisis response and reporting tools stack up, Lumina included.
Because that’s really the mindset shift comms teams, and the firms advising them both need to make. As Takeo put it on the IABC APAC and Isentia webinar: “I fear that this is the mindset shift communications teams and their advisors must adopt. I fear that AIs will be your secondary, and if not, at least equal… audience in the future.” Beyond human visibility, reputation is about being accurately represented by the systems that mediate access to your audience, which is an additional layer that cannot be trivialised anymore.
"
["post_title"]=>
string(97) "How relevant is Tier 1 and Tier 2 media hierarchy in impacting how organisations show up in LLMs?"
["post_excerpt"]=>
string(243) "The hierarchy that exists between Tier 1 & 2 publications today is being challenged. AI models are the new way audiences discover information requiring organisations to rethink how they show up to remain visible in an AI-mediated environment. "
["post_status"]=>
string(7) "publish"
["comment_status"]=>
string(4) "open"
["ping_status"]=>
string(4) "open"
["post_password"]=>
string(0) ""
["post_name"]=>
string(96) "how-relevant-is-tier-1-and-tier-2-media-hierarchy-in-impacting-how-organisations-show-up-in-llms"
["to_ping"]=>
string(0) ""
["pinged"]=>
string(0) ""
["post_modified"]=>
string(19) "2026-09-09 02:24:17"
["post_modified_gmt"]=>
string(19) "2026-09-09 02:24:17"
["post_content_filtered"]=>
string(0) ""
["post_parent"]=>
int(0)
["guid"]=>
string(32) "https://www.isentia.com/?p=49871"
["menu_order"]=>
int(0)
["post_type"]=>
string(4) "post"
["post_mime_type"]=>
string(0) ""
["comment_count"]=>
string(1) "0"
["filter"]=>
string(3) "raw"
}
Blog
How relevant is Tier 1 and Tier 2 media hierarchy in impacting how organisations show up in LLMs?
The hierarchy that exists between Tier 1 & 2 publications today is being challenged. AI models are the new way audiences discover information requiring organisations to rethink how they show up to remain visible in an AI-mediated environment.