Blog
NZ Election 2026: Welfare, Greens and the policies driving conversation
What’s shaping New Zealand’s 2026 election conversation? Explore the key policies, parties and issues driving media and social discussion this week.
The upcoming Philippines National Election has created heightened media chatter about the involvement of politicians within the community. While some of this news was met with positive sentiment, there were many comments filled with skepticism and doubt.
In this whitepaper, we explore how social media conversations spark opinions and discourse on the upcoming 2022 Philippine National Elections and beyond.
Download the whitepaper and read more.

Loren is an experienced marketing professional who translates data and insights using Isentia solutions into trends and research, bringing clients closer to the benefits of audience intelligence. Loren thrives on introducing the groundbreaking ways in which data and insights can help a brand or organisation, enabling them to exceed their strategic objectives and goals.
A weekly tracker tracing the stories, figures and policies driving media and social coverage in the 2026 New Zealand General Election across Online News, TV, Radio, Newspaper, Magazine, X, Facebook, Instagram, TikTok, Threads and Forums. This edition covers conversations and coverage from 1st – 8th October, highlighting what’s shaping the election conversation.
National announced a five-point welfare policy: random drug testing for JobSeeker recipients (with sanctions for repeat failures), reduced payments for long-term beneficiaries, and a doubled stand-down period for repeatedly leaving jobs without good reason. Labour and the Greens called it "punching down" and "cruel"; ACT proposed going even further; Luxon defended it as "fairness" for taxpayers.
The single largest media cluster this week (183 of 600 sampled items) was generic "campaigning intensifies as election day nears" coverage. This welfare policy, while smaller by volume (29 items), is a genuine flashpoint: a specific, controversial announcement that sharply divided every major party and will likely keep generating reaction into next week.
4,360 media items · 17,277 social items · share of each channel's own conversation, so the two bars are directly comparable
The Greens get more than twice the relative attention on social media as in the news. On social, the Greens are 20.8% of party conversation; in the news, they're 10.3%.
Health is a top-four issue on social but not in the news this week - Infrastructure takes its place in media's top four instead. Social conversation is tilting toward the health system while media coverage stays on economy, cost of living and infrastructure announcements.
Share of conversation measures attention and mentions only - it is not polling and should not be read as an indication of electoral success.
Luxon and Hipkins remain close at the top as the campaign enters its final stretch. Peters follows, still driven by coalition speculation. Seymour moves up to fourth on the back of ACT's economic-reform push (including floating a higher superannuation age), overtaking Swarbrick, whose fifth-place mentions continue to track the Greens' polling strength.
Each major party's most prominent specific policy, and how social conversation reacted to it
Volume and sentiment above are based on social media data only.
If you want to find out more about how Isentia can help you understand the NZ media landscape, please reach out to us here.
" ["post_title"]=> string(71) "NZ Election 2026: Welfare, Greens and the policies driving conversation" ["post_excerpt"]=> string(152) "What’s shaping New Zealand’s 2026 election conversation? Explore the key policies, parties and issues driving media and social discussion this week." ["post_status"]=> string(7) "publish" ["comment_status"]=> string(4) "open" ["ping_status"]=> string(4) "open" ["post_password"]=> string(0) "" ["post_name"]=> string(69) "nz-election-2026-welfare-greens-and-the-policies-driving-conversation" ["to_ping"]=> string(0) "" ["pinged"]=> string(0) "" ["post_modified"]=> string(19) "2026-10-08 12:06:35" ["post_modified_gmt"]=> string(19) "2026-10-08 12:06:35" ["post_content_filtered"]=> string(0) "" ["post_parent"]=> int(0) ["guid"]=> string(32) "https://www.isentia.com/?p=50341" ["menu_order"]=> int(0) ["post_type"]=> string(4) "post" ["post_mime_type"]=> string(0) "" ["comment_count"]=> string(1) "0" ["filter"]=> string(3) "raw" }What’s shaping New Zealand’s 2026 election conversation? Explore the key policies, parties and issues driving media and social discussion this week.
A customer evaluating a brand, a journalist researching a CEO, and a policymaker looking up a public agency are all doing the same thing — discovering organisations through AI. The difference is that they may each receive a different description, supporting evidence, and overall impression.
This shift represents a major change in modern communications.
Large language models (LLMs) now interpret information for audiences, rather than just helping them find it. Instead of listing search results, they retrieve content, select authoritative sources, and generate a single synthesised answer that many users accept without reviewing the original articles.
For PR, communications, and marketing professionals, this presents a new reputation challenge. Your organisation now has multiple AI-generated reputations, each shaped by the model your stakeholders use. Understanding these differences is becoming as important as understanding media coverage – in fact, the two are often closely linked.
A common misconception is that ChatGPT, Gemini, Claude, and Perplexity all access the same information. In reality, they don’t.
At a high level, all leading LLMs are built on similar foundations. They're trained on vast collections of books, websites, news articles, public documents and licensed datasets that help them understand language and generate human-like responses. Increasingly, they're also capable of retrieving live web information, allowing answers to incorporate recent events rather than relying solely on historical training data.
However, their similarities end there.
Each LLM uses a unique combination of training data, retrieval architecture, and ranking logic. As a result, each model answers three key questions differently before generating a response:
These decisions fundamentally shape how organisations are represented. To explain this better, we summarise how different AI models consult different publications and finally cite them in AI answers:
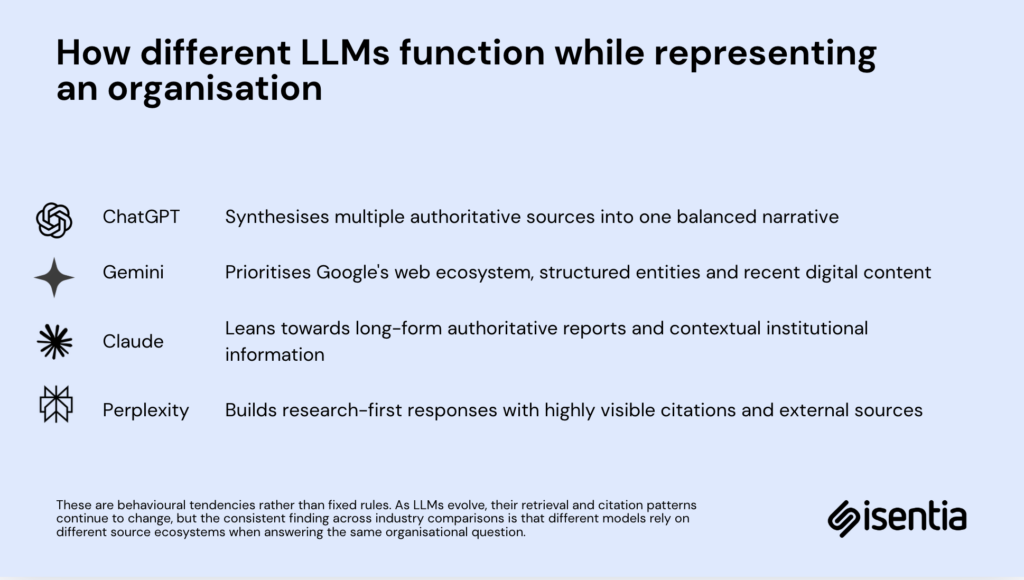
LLMs are not impartial, but come with their own weights and balances. In a sense, it reflects dynamics we already see at play across PR & Comms.
If four experienced journalists had to write a profile of the same CEO after attending the same press conference and have access to the same reports, one may write about leadership, another financial performance, another governance and another might frame the story around innovation. None are necessarily wrong—they're simply viewing the event through a lens of individual expertise, and therefore, making different editorial decisions.
LLMs behave in similar ways. As a result, organisations are now represented by multiple AI-generated narratives, rather than a single authoritative digital narrative.
These differences are most apparent when users ask AI questions that require judgment rather than simple factual recall.
Consider a prompt like: "Which are the leading banks in Southeast Asia?" Across ChatGPT, Gemini, Claude, and Perplexity, you will likely see many of the same names — DBS, UOB, OCBC, and Maybank. This overlap occurs because all four models recognise these institutions as major regional banks.
However, the models differ in their explanations of why these banks are considered leaders.
ChatGPT may highlight DBS's digital banking leadership and customer experience. Claude is potentially more likely to discuss governance, regional strategy, and long-term institutional strength. Gemini may emphasise recent awards and publicly available web information, while Perplexity often presents answers as research comparisons supported by multiple citations. These changes are not necessarily so big as to be immediately noticeable, but over time the results accumulate.
An organisation may not meaningfully change between two users asking two different LLMs , but the reputation narrative shifts accordingly. This distinction matters because stakeholders rarely ask AI for isolated facts. They ask questions like:
AI responds by interpreting credibility, authority, and context, rather than simply retrieving documents.
For communications teams, this means your organisation is increasingly evaluated through comparative prompts, where competitors, industry peers, and institutional benchmarks appear alongside your organisation by default.
When ChatGPT, Gemini, Claude, or Perplexity answer a question, they first retrieve documents from distinct information ecosystems. A recent study analysed 17.2 million AI citations across ChatGPT, Gemini, Claude and Perplexity and found that each model retrieves from substantially different source ecosystems rather than a shared pool of webpages. Two LLMs can answer the same question accurately while relying on entirely different publications.
Instead of viewing these as technical differences, it is more useful to consider them as citation behaviours. Each model consistently references different types of publications when explaining organisations.
ChatGPT functions more like an executive briefing writer than a traditional search engine.
Rather than listing multiple links, ChatGPT typically combines information from several credible publications into a coherent narrative. If mainstream media, company information, and industry commentary consistently describe an organisation as a market leader, ChatGPT is likely to reinforce that positioning, regardless of the original source.
For a prompt like "Tell me about Singapore Airlines”, a typical ChatGPT response integrates its history, customer experience, awards it has won over time, its financial performance, etc., into a cohesive description. Individual articles become almost invisible, as the model prioritises a coherent narrative in its answer over transparently showcasing all citations.
For brands, this means consistency across publications is very valuable. ChatGPT values credible signals that repeat across multiple publications over one off news moments.
Gemini approaches organisations differently, as its retrieval is closely linked to Google's broader information ecosystem.
When we ask "What has Enterprise Singapore done to support AI businesses?", Gemini is more likely to include recent programme announcements, official government webpages, and newer online reporting. Its responses often feel more current because they draw from a web ecosystem designed to reflect continuously updated information.
For government agencies, this has practical implications. Official announcements and well-structured public information become machine-readable assets that help AI explain policy more accurately. These become important information touchpoints into how audiences understand government through AI.
Claude's defining feature is its emphasis on context.
Other models often prioritise concise answers but Claude frequently elaborates on why an organisation is respected. Questions about leadership, governance, ethics, and institutional reputation tend to produce more detailed explanations rather than brief summaries.
For a prompt like "Why is DBS considered one of Asia's leading banks?", Claude is more likely to discuss how the bank has regionally expanded, its digital transformation, what’s unique about its leadership etc. Its responses resemble analyst reports more than search summaries, as it favours high-authority editorial and institutional content.
For executive communications, this makes Claude particularly influential. Leadership narratives and corporate values often receive more contextual treatment than with other models.
Perplexity changes the experience by treating citations as a central feature rather than a supporting detail.
A question comparing two sustainability leaders, for example, typically returns numerous linked sources from business media and research publications. Users can immediately review the origin of each claim.
For PR teams, this creates greater transparency. Publication quality becomes visible within the user experience and is not hidden behind an AI summary. This means media strategy influences the evidence presented alongside the perception of the organisation.
Although LLMs behave similarly across sectors, the questions users ask differ fundamentally.
Consumers rarely ask AI what a brand does. They definitely do ask which brand is better.
Questions like:
1. Which airline has the best customer experience?
2. Is Salesforce better than HubSpot?
3. Which bank is most innovative?
4. Who are the leaders in cloud computing?
These questions are inherently comparative.
As a result, your organisation is often introduced alongside competitors before stakeholders visit your website.
During a recent Isentia webinar on Measuring your brand’s visibility in AI answers, we analysed airlines across multiple LLMs with Lumina AI View. Using identical prompts, different models highlighted different airlines and emphasised varying strengths, such as premium service, operational performance, innovation, and customer experience. Competitive positioning shifted depending on the model, even though the underlying organisations remained unchanged.
For commercial communicators, competitor association is becoming as important as share of voice. AI evaluates brands in context, not in isolation.
Public sector organisations encounter a different reputational challenge. Audiences increasingly ask questions that begin with how, why and can I trust:
1. What support does this agency provide?
2. Has this ministry achieved its policy goals?
3. What AI initiatives has this department introduced?
4. Has this programme faced criticism?
LLMs then synthesise official publications and institutional information into a single accessible explanation. This changes the role of public communications. The objective is not to ensure AI models have sufficient credible, authoritative context to explain complex policy accurately.
As AI becomes the primary interpreter of government information, communications teams are responsible for managing both visibility and understanding.
Reputation has been shaped across three familiar environments: media, search and social. AI introduces a fourth environment.
LLMs condense dozens of publications into a single response, reducing the traditional discovery process between a question and an opinion.
During the recent webinar, Prashant Saxena, VP of Revenue and Insights says, “We used to Google it. Now we're ChatGPT-ing it.”
This behavioural shift is significant. Reuters Institute research found that only a small proportion of AI chatbot users regularly click through to original articles.
Practically, every piece of earned coverage now has two audiences:
Both shape reputation.
This is the challenge Lumina AI View was designed to solve.
Instead of measuring whether an organisation appears in ChatGPT, AI View measures how different LLMs represent the organisation. Using consistent question sets across ChatGPT, Gemini, Claude, Perplexity, Grok, and Google AI Overviews, it compares narratives, citations, and competitive positioning through a unified reputation methodology.
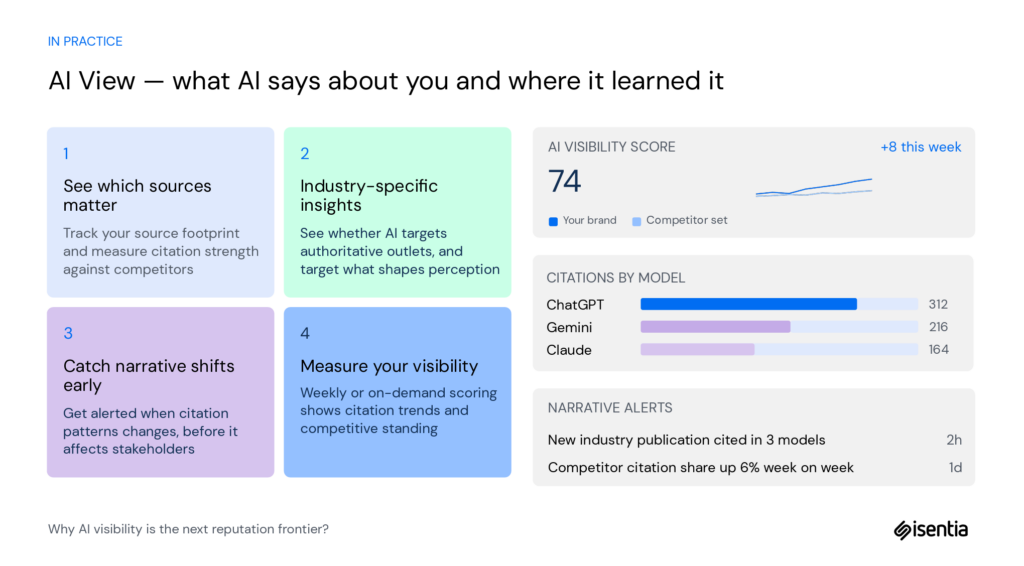
The framework is built around four familiar dimensions: Direction, Performance, Integrity, and Innovation. Rather than tracking keywords alone, AI View identifies which reputation pillars dominate AI responses, which publications influence those narratives, and how representation differs across models. It also gives the organisation an AI score based on all the above factors.
The tool also shows organisations which publications are covered by different AI models. If the organisation’s AI score on the tool is high for ChatGPT, but struggles with or is a lower score on Gemini or Perplexity, the tool allows you to see where you’re underperforming. If there are publications that are covering the wrong information, or the important ones just don’t show up, then that’s an indication to why the AI score is low on that platform.
The communications profession has always adapted to new discovery channels, from newspapers to search engines, and from social media to digital news.
AI is different because it does not simply help audiences find information, but it increasingly determines how organisations are introduced.
For communications leaders, this changes media strategy in three key ways.
Organisations that succeed in this new environment are those that have leadership, performance, integrity, and innovation represented consistently across every major AI model, regardless of where audiences and stakeholders begin their search.
Want to see which sources are shaping how AI describes your organisation? Get in touch about Lumina AI View.
" ["post_title"]=> string(50) "How do different LLMs represent your organisation?" ["post_excerpt"]=> string(136) "Uncover how different LLMs treat your brand, explore key model capabilities, and learn how PR teams can measure and shape AI visibility." ["post_status"]=> string(7) "publish" ["comment_status"]=> string(4) "open" ["ping_status"]=> string(4) "open" ["post_password"]=> string(0) "" ["post_name"]=> string(49) "how-do-different-llms-represent-your-organisation" ["to_ping"]=> string(0) "" ["pinged"]=> string(0) "" ["post_modified"]=> string(19) "2026-09-21 02:42:00" ["post_modified_gmt"]=> string(19) "2026-09-21 02:42:00" ["post_content_filtered"]=> string(0) "" ["post_parent"]=> int(0) ["guid"]=> string(32) "https://www.isentia.com/?p=50056" ["menu_order"]=> int(0) ["post_type"]=> string(4) "post" ["post_mime_type"]=> string(0) "" ["comment_count"]=> string(1) "0" ["filter"]=> string(3) "raw" }Get in touch or request a demo.